«AI Writes Code, but a Human Still Has to Run the Project» — No. The Entire SDLC Runs on Agents Now

Requirements, planning, infra, CI/CD, tests, monitoring — every step of the cycle, pinned to a specific tool and a production case. No human in the loop required.

I read this opinion ten times a week. Okay, the argument goes, AI can write code — fine. But to actually run a project, you need a human: talk to stakeholders, write a plan, set tasks for that same AI, configure infrastructure, Git, servers, monitoring. And surely no one is replacing the human there!

My eyes roll back every time. What?

Let me walk through the entire cycle. Step by step. At every step, I will show you not a fantasy, but a specific practice with a tool underneath it — because I have already run this cycle hands-on.

Continue reading “«AI Writes Code, but a Human Still Has to Run the Project» — No. The Entire SDLC Runs on Agents Now”

Enabling Blocks Network inside a conservative enterprise — the plumbing you have to build before an agent network is even allowed

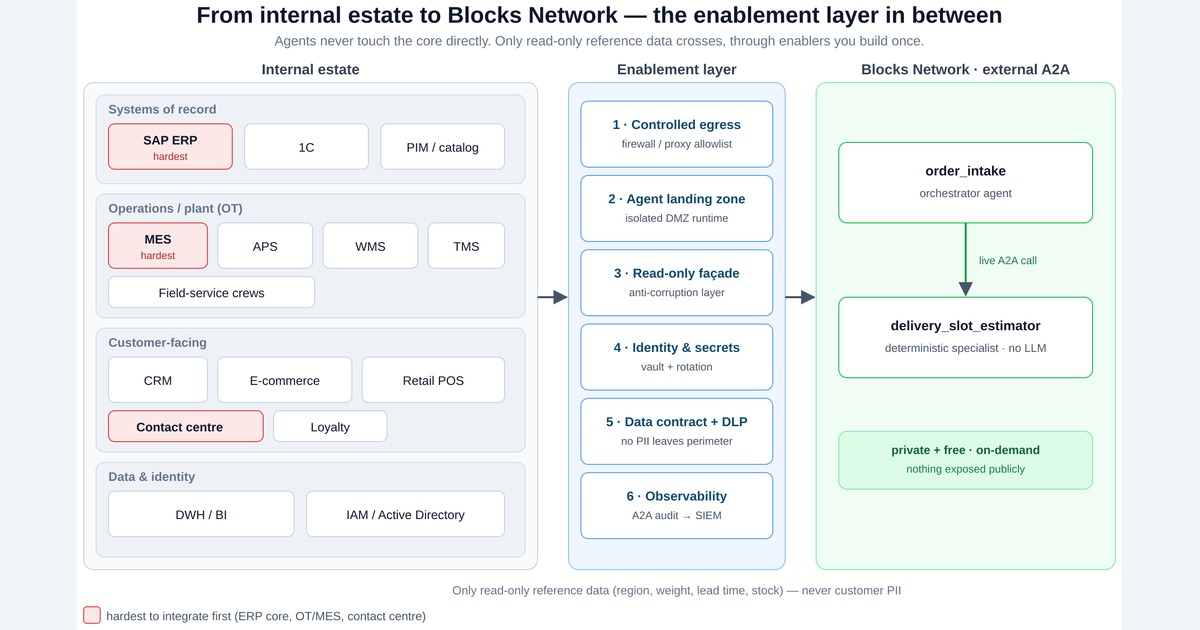
An enablement playbook for a large, risk-averse, vertically integrated company — mapping the internal estate, naming the systems you won’t crack first, and building the egress, identity, façade and audit layers that turn “nice demo” into “approved pilot.”

The easy version of "adopt an agent network" is a demo on a laptop. The hard version is the one that pays: getting that network approved, piloted and scaled inside a big, conservative company that has a lot to lose.

Picture the archetype. A vertically integrated manufacturer-retailer: its own factories, its own warehouses and trucks, its own stores, its own contact centre. The IT estate is mature but heavy — an ERP at the core, a patchwork of line-of-business systems around it, home-grown glue holding the seams together. There is a security function with veto power, a procurement function that owns the contract, and a culture whose first instinct is "prove this won't break sales during peak season."

This is a playbook for that company. Not the marketing pitch — the actual sequence of questions you get asked, in the order you get asked them, and the honest answer to each. I'll keep the vendor's claims, the things I verified in a build, and the things that are spec-only strictly separate, because in a room like this, blurring them is how you lose the room.

Continue reading “Enabling Blocks Network inside a conservative enterprise — the plumbing you have to build before an agent network is even allowed”

Building on Blocks Network — a hands-on field report on the “Internet of Agents”

Two agents, one live agent-to-agent call, and an honest engineering read for developers, DevOps, analysts and security teams.

Every team I work with is suddenly shipping AI agents. The agents are the easy part. The hard part — the part I spent years solving for ordinary services — is the layer underneath: how does an agent built by one team get discovered, called, and governed by another, without everyone rebuilding the same plumbing and without security signing off on a free-for-all?

Blocks Network (from PubNub) pitches itself as exactly that substrate — a network for agent-to-agent communication with routing, discovery, presence and an economy layer. So instead of reading the marketing, I built on it. This is a field report from taking it from npm install to a live two-agent call, written for the four people who actually have to approve this kind of thing: the developer, the DevOps/platform engineer, the analyst/architect, and the security reviewer.

Everything below is what I observed on the real platform on a Linux box (Node v20.19.5, Blocks CLI 1.0.24). Where I couldn't verify something, I say so.

Continue reading “Building on Blocks Network — a hands-on field report on the “Internet of Agents””

Process Over Agent: How I Put an ECC Harness Through a Real Refactor

A coding agent without a harness is a fast, forgetful junior. The problem isn’t generation speed — it’s the absence of process around it.

Eighteen months ago I would have written this post about speed. About how an agent drafts in a minute what used to take me an hour. Today I'm writing it about discipline — and that shift is the whole story of the past year and a half.

I've been living in a mode where a coding agent writes a significant portion of my code for about eighteen months now. First came exhilaration, then fatigue, then a sober realization: an agent without a harness is not an engineer. It is a very fast, very forgetful junior. It can draft in a minute what would take me an hour, but in that same minute it will cheerfully take out a neighboring module, skip the tests, invent a library method that doesn't exist, and forget what we agreed on five messages ago. As a technical manager, I look at this plainly: the problem is not code generation speed. The problem is the absence of process around that generation.

Continue reading “Process Over Agent: How I Put an ECC Harness Through a Real Refactor”

The Monorepo Cargo Cult: You Broke Your Architecture for an Illusion

Developers are physically merging separate projects into one git repository because they think it helps AI agents read code. It doesn’t. You’re paying a real architectural price for an imaginary benefit.

I ran into a misguided pattern going by the terrifying name "the monorepo." People are seriously merging different projects into a single physical git repository because they think it makes it easier for an agent to "walk the files" and understand the overall context of a large corporate system. Dozens of comments under the post: oh yes, we started doing this too, excellent mechanism, everyone is happy.

This is the wrong abstraction boundary.

Continue reading “The Monorepo Cargo Cult: You Broke Your Architecture for an Illusion”

The AI Agent Protocol Stack: A Map of the Layers

From text generation to autonomous agents — and the emerging protocol stack that makes multi-agent engineering possible.

Since 2022, systems built on large language models have moved from "generate a paragraph" to autonomous agents. In production, an AI agent usually wraps an LLM with tool calls, state, and orchestration. It is an autonomous module that combines three capabilities: planning (breaking a goal into steps), memory (short-term in context, long-term in external stores), and execution (calling APIs, writing files, triggering other services).

In production deployments, teams run into interface fragmentation. The model lives in one place, the tools in another, other agents elsewhere, and the corporate security perimeter somewhere else entirely. All of these must be wired together. The classic formulation of this pain is the N×M problem: connecting N clients to M data sources requires writing N×M unique adapters. Five models and ten tools turn into fifty hand-coded connectors that nobody wants to maintain.

Vendors and open-source projects are proposing several protocol families. Several protocols now target different parts of agent integration — specifications that each take over a specific piece of the wiring: how the model reaches a tool, how an agent lives in time, how two agents negotiate, how data safely crosses the perimeter. Below is a breakdown of ten such protocols and standards, grouped by architectural layer.

Continue reading “The AI Agent Protocol Stack: A Map of the Layers”
The Self-Learning Agent Pattern: decisions.md + mistakes.md

AI keeps repeating the same mistakes? That’s not a model problem. It’s an engineering gap. How to give your agent persistent memory in three minutes — and why this beats RAG for most projects.

Developers complain that AI repeats the same mistakes. "I've explained five times that we don't use Redux here." "It suggested FTP again instead of a queue." "It keeps ignoring our naming conventions."

That's not a model problem. It's an engineering gap.

Continue reading “The Self-Learning Agent Pattern: decisions.md + mistakes.md”

AI Is Not Just a Coder: How AI Covers the Entire Software Development Lifecycle

‘AI is just a very fast intern coder’ is an accurate description of stage one. At stage two, AI becomes an executor of thinking at every step of the SDLC — from clarify dialogs with stakeholders in Jira to multi-agent pipelines that catch, fix, and verify themselves.

"Writing code is only a small part of the SDLC. There's also stakeholder interviews, requirements formulation, architectural design, testing, monitoring. AI is just a very fast coder — not a thinking member of the team."

That argument is right. For stage one.

At stage one, someone watches AI write code and concludes: "AI = coder." Then they notice that coding isn't the whole of software development. "Therefore AI won't replace engineering entirely." The logic holds. The conclusion doesn't.

At stage two, AI covers exactly what that argument says is missing.

Continue reading “AI Is Not Just a Coder: How AI Covers the Entire Software Development Lifecycle”

AI Job Demand in 2026: What Hiring Signals Show in Job Postings

Hype says “hire AI.” Job descriptions buy something else: production agents with evals and guardrails, Applied AI leadership, partner architecture, evaluation harness as a must-have. Method: read role clusters as an org chart under pressure.

Hype says “hire AI.” Real job descriptions buy people who own production agents, evals, Applied AI, and partner delivery. Below is a method for reading vacancy clusters as an org chart under pressure, plus five role clusters from a parsed corpus of open roles.

Continue reading “AI Job Demand in 2026: What Hiring Signals Show in Job Postings”

Why AI skills need onboarding if you can just copy them into the folder

Three skills are fine. Thirty — style drifts, shared state gets overwritten, behavior changes with no stack and no log line. Dropping markdown into `.claude/skills/` is a hire with no interview. Onboarding exists so you catch the conflict before it hits daily flow — not because process looks nice.

Because copying markdown into a folder is not installing a package. It is a hire: a new slice of behavior enters the assistant and will collide with its neighbors tomorrow. A skill here is an instruction pack for an AI assistant (Claude Code / Cursor): frontmatter, rules, declared reads/writes/calls. While the intake path is empty, every new file under .claude/skills/ is a silent hire with no interview and no record in the file.

Continue reading “Why AI skills need onboarding if you can just copy them into the folder”